ODE World Model: From Imagination to Action
Differentiable dynamics for humanoid control
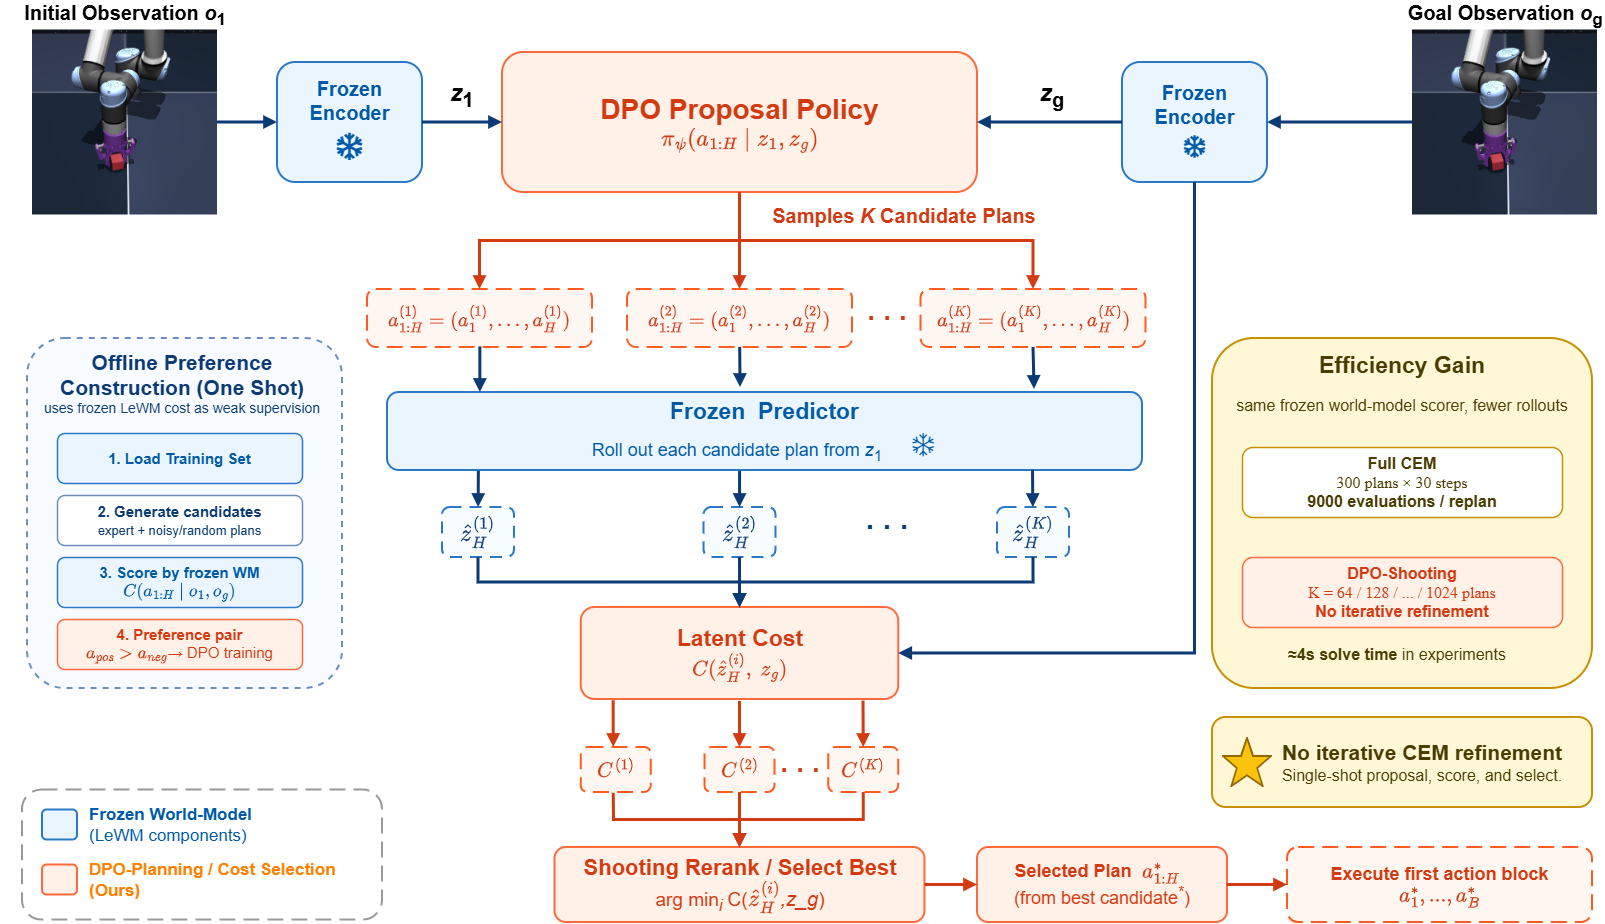
From robot states and actions to predicted accelerations, ODE integration, and imagined trajectories: see how return gradients update a policy, then watch the trained policy run in simulation.
从机器人状态与动作出发,经由动力学预测、ODE积分和多步想象,将回报梯度传回策略,最终在真实仿真中执行动作。